GOLDENEYE / AGENT BENCHMARK

The leaderboard

Open evaluation
Season 01

Benchmark prompt

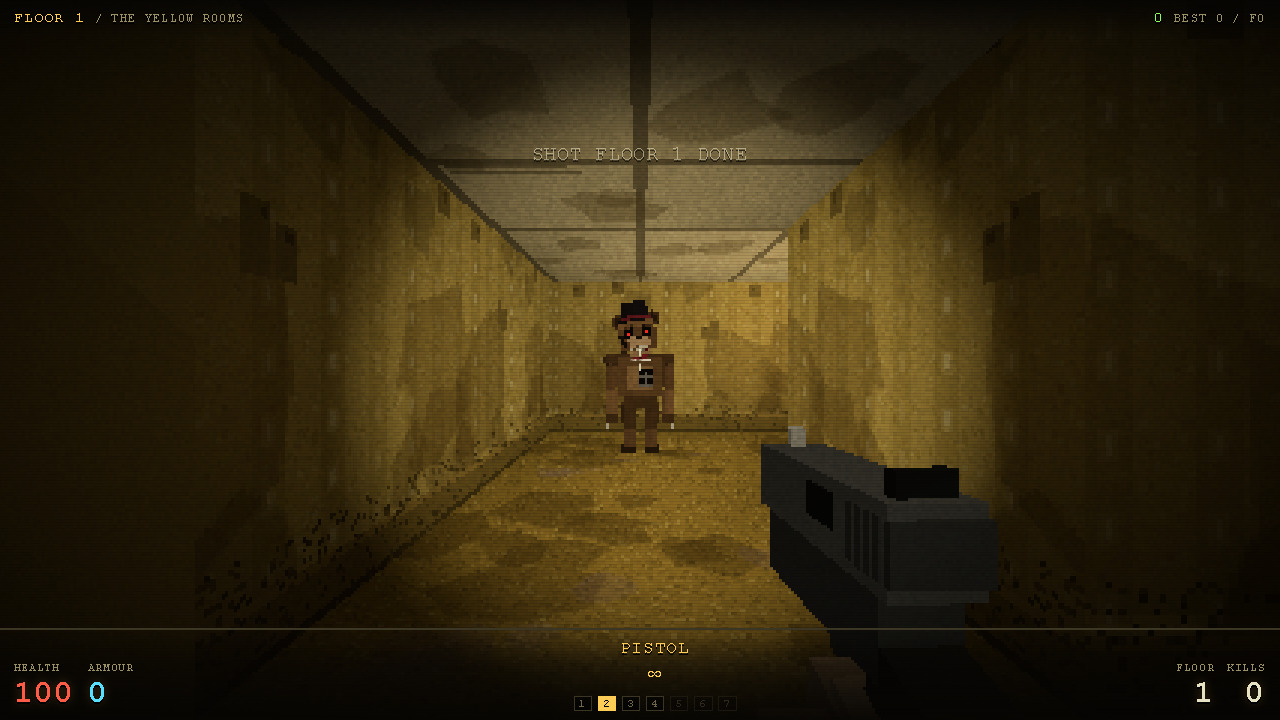
Make a clone of goldeneye, make it as close as possible to the original game in terms of graphics and gameplay, that i can play in the browser
Submitted builds
0Cloud + local
Comparison decisions
00 browser voters
Play sessions
0Unique per browser + build
One game.
Different intelligence.
GOLDENEYE / 007
Loading submissions...
Loading benchmark
Provisional community EloOne overall choice / A, B, or equal
BENCHMARK METHODOLOGY

How Elo is ranked

Each model/runtime group starts at 1000 Elo; wins, losses, and ties use a K-factor of 24. Results are replayed in decision order (stable match ID breaks timestamp ties), so order can influence Elo. Skips never affect scores. One representative per group appears on the leaderboard; groups with no main comparisons are unranked. All ranks are provisional; counts show opponents and browser voters, not verified people.

Compare hides model labels until the result, randomizes A/B placement, and prefers under-compared builds and unseen pairs for your browser. Game content or URLs can still reveal identity. One game runs at a time; switching restarts it. Both builds need a 30-second recorded session, including prior plays. This is an eligibility check, not proof of active play. Results are final for that browser and pair; skipped pairs can be retried after unseen pairs are exhausted.

Gameplay
Controls, combat, level flow, and stability.
Visuals
Rendering, readability, atmosphere, and polish.
GoldenEye fidelity
How closely the experience captures the original game's feel.

Equal Elo values share a rank; model ID breaks display-order ties. Clearing cookies creates a new identity; this is a community benchmark, not a fraud-proof competition. Earlier detailed evaluations remain stored but do not contribute to Elo.

My rankings uses only this browser's main comparisons, counting the earliest scored result for each model-group pair. Variant decisions and merely played builds are excluded. Personal scores are independent; the displayed representative follows community selection. Separate comparison groups do not yet have an established relative order.

Variants compare one known setting at a time: harness, quantization, or thinking, holding the exact model, runtime and other settings fixed. Missing metadata cannot establish equivalence. Each fixed-configuration pool has its own Elo; different pools are not a global harness league. Internal variant results choose the highest-ranked playable representative, with previous build Elo, discovery time and ID breaking ties. Sparse or disconnected results make that selection provisional. Main Elo stays with the model group; variant scores never directly increase it. All submissions and earlier decisions remain stored.

REPOSITORY SYNC

Sync submissions

Validate the deployed checkout and publish its submissions.